
Ollama Configuration
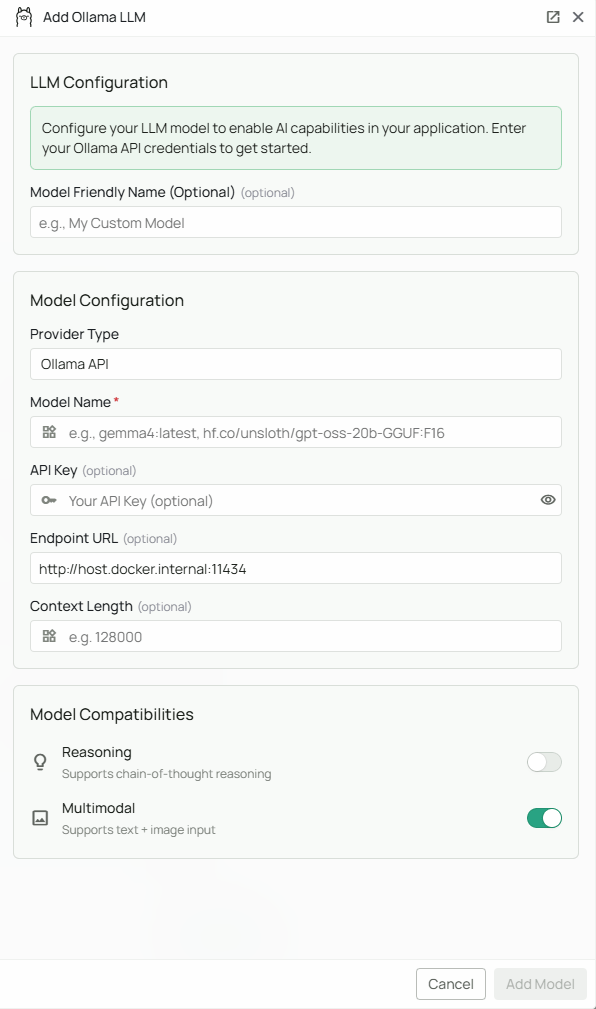
Required Fields
Model Name *
The Model Name field defines which Ollama model you want to use with Novaplan AI. Popular Ollama models include:gemma4:latest- Google’s Gemma 4 modelhf.co/unsloth/gpt-oss-20b-GGUF:F16- A Hugging Face-hosted GGUF model
- For multimodal capabilities (text + images), select models with vision support
- Check Ollama’s model library for the complete list of available models
Optional Fields
Endpoint URL
The Endpoint URL specifies where your Ollama instance is running. Defaults tohttp://host.docker.internal:11434 if left blank.
Common configurations:
http://host.docker.internal:11434- Application default; use only if Novaplan confirms that this hostname resolves to your Ollama service from the workspacehttps://your-server-domain- Example of a separately hosted, reachable Ollama service
11434 by default.
Note: Your computer’s localhost is not automatically reachable from a managed Novaplan AI workspace. Confirm the endpoint with Novaplan before configuring it.
API Key
The API Key field is optional for Ollama configurations. Most local Ollama instances do not require authentication. When to use:- If you’ve configured authentication on your Ollama instance
- When connecting to a secured remote Ollama server
- For enterprise deployments with access control
Advanced Options
Multimodal Support
Enable the Multimodal checkbox if your selected model supports both text and image inputs. Multimodal-capable models include:qwen3-vl:8b
- Novaplan AI can send both text and image data to the model
- Supports use cases like image analysis, visual question answering, and document understanding
Reasoning
Enable the Reasoning checkbox if your selected model has enhanced reasoning capabilities. When enabled:- The model will be used for tasks requiring complex logical reasoning
- Better performance on multi-step problem solving
- Enhanced analytical capabilities
Configuration Steps
As shown in the image above:- Click Configure on the Ollama provider card
- Enter your Model Name (marked with *) — e.g.,
gemma4:latestorhf.co/unsloth/gpt-oss-20b-GGUF:F16 - (Optional) Specify your Endpoint URL — defaults to
http://host.docker.internal:11434 - (Optional) Enter an API Key if your Ollama instance requires authentication
- (Optional) Check “Multimodal” if your model supports text + image processing
- (Optional) Check “Reasoning” if your model has enhanced reasoning capabilities
- Click Add Model, then test a request from the managed workspace
Model Name is the only required field. The endpoint defaults to http://host.docker.internal:11434 if left blank. No API key is required for a standard local Ollama installation.
Prerequisites
Before configuring Ollama in Novaplan AI, coordinate with the model-server operator to ensure:-
Ollama installed on the agreed model server
- Download from ollama.com
- Follow installation instructions for your operating system
-
Model downloaded - Pull your desired model:
-
Ollama running - Start the Ollama service:
- Network accessibility - Ask Novaplan to verify that the managed workspace can reach your Ollama endpoint
Usage Considerations
Advantages of Ollama
- Data location: Processing occurs on the Ollama server your organization or Novaplan provides; confirm its location and access controls before use
- Cost planning: A self-hosted Ollama server does not charge per local API request, but its compute, storage, network, and Novaplan service costs still matter. Hosted Ollama or a gateway can have separate charges and limits.
- Customizable: The model-server operator controls the models and server configuration
- Network-dependent: The managed workspace must maintain access to the Ollama server
- Capacity-dependent: Throughput can be limited by hardware, server settings, a gateway, or workspace policy
System Requirements
- Sufficient RAM or GPU memory for the selected model; check its published requirements
- Modern CPU or GPU for optimal performance
- Adequate disk space for the selected model and its variants
Performance Tips
- Use GPU acceleration when available for faster inference
- Choose smaller models for quicker responses if your use case allows
- Consider a smaller or quantized model if memory or response time is constrained
Troubleshooting
Connection Issues
- Verify Ollama is running: Run
ollama listin your terminal - Check endpoint URL: Ensure the URL matches where Ollama is accessible
- Firewall settings: Verify that port 11434 is not blocked
- Managed workspace routing: Ask Novaplan to verify the endpoint and network path; the default
host.docker.internalmay not resolve in your workspace
Model Issues
- Model not found: Ensure you’ve pulled the model with
ollama pull <model-name> - Out of memory: Try a smaller or quantized version of the model
- Slow performance: Consider using a GPU
Multimodal Issues
- Images not processing: Verify your selected model supports vision capabilities
- Check model documentation: Not all models support multimodal inputs
Available Models
Visit the Ollama Model Library to browse all available models, including:- Language models (LLMs)
- Code-specialized models
- Multimodal models (vision + language)
- Embedding models
- Quantized variants for efficiency