
Whisper (Local) Speech to Text Configuration
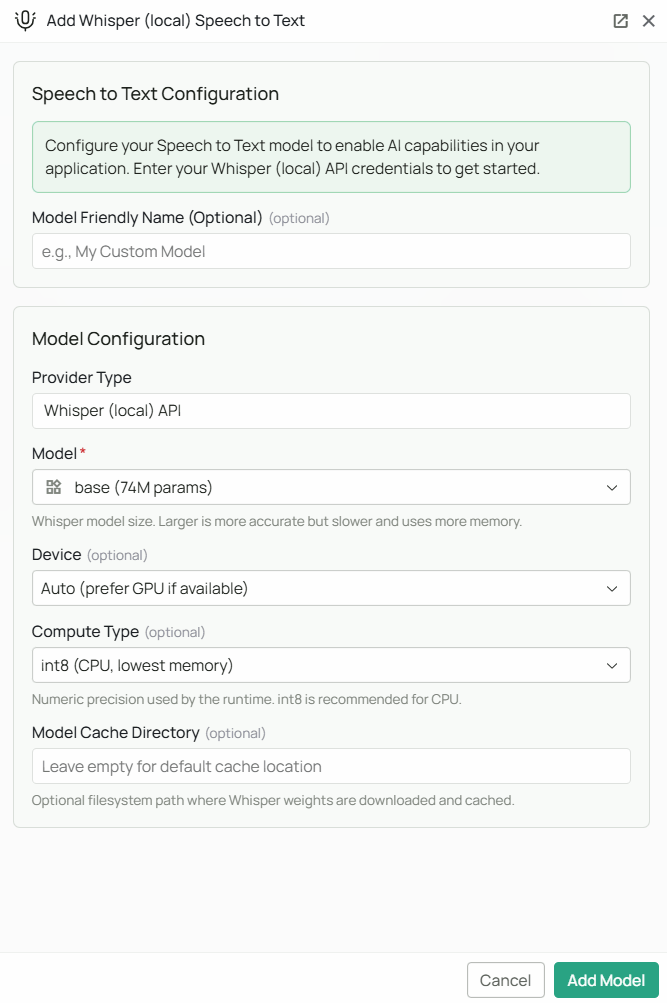
faster-whisper library in the managed workspace backend. This option does not require a third-party transcription API key. Audio is processed by that backend rather than sent to a separate speech-to-text API; confirm your workspace’s hosting and data-handling arrangements with Novaplan if you have specific residency requirements.
Whisper model weights are downloaded from Hugging Face on first use. Novaplan manages backend connectivity, package installation, storage, and compute capacity for your workspace. Contact Novaplan Support if model setup or the health check fails.
Required Fields
Model *
Select the Whisper model size from the dropdown. Larger models are more accurate but require more memory and processing time.
How to choose a model size:
- For real-time voice input where speed matters most, start with
baseorsmall - For high-accuracy transcription of important audio, use
distil-large-v3orlarge-v3 - If your managed workspace has a GPU available, larger models may be practical; confirm capacity with Novaplan
Optional Fields
Device
Controls which hardware the model runs on.- Auto (default) — Novaplan AI automatically uses a GPU if one is available, otherwise falls back to CPU
- CPU — forces CPU inference on the workspace backend
- CUDA — uses a compatible NVIDIA GPU on the workspace backend, if provisioned
Compute Type
Controls the numerical precision used during inference. Lower precision uses less memory and runs faster; higher precision is more accurate.Model Cache Directory
A filesystem path on the managed backend where downloaded model weights will be stored. Leave blank to use the faster-whisper default cache location. Ask Novaplan before setting a custom path, since it must exist and be writable in your workspace environment. Example:/data/whisper-models
Novaplan can use this setting when it provisions a dedicated model cache or the default location has limited storage.
Configuration Steps
As shown in the image above:- Click Configure on the Whisper (Local) provider card in the STT tab
- Select your desired Model size from the dropdown (marked with *)
- (Optional) Set Device — leave on Auto unless you need to force CPU or GPU
- (Optional) Set Compute Type — leave on
int8for CPU orint8_float16for GPU - (Optional) Set a Model Cache Directory to control where weights are stored
- (Optional) Set a Model Friendly Name
- Click Add Model to save your configuration
On first use after saving, Novaplan AI will download the selected model weights from HuggingFace. This may take several minutes depending on model size and network speed.
Usage Considerations
- No separate third-party transcription API charge for this provider; managed compute and storage are still part of your service arrangement
- The
large-v3model requires approximately 3 GB of disk space and at least 4 GB of VRAM (or 8 GB of RAM for CPU inference) distil-large-v3is a faster large-model option; test accuracy and latency with your own audio before selecting it- First use requires the managed backend to download model weights; later transcription does not require a third-party transcription API, though other workspace functions may still need network access
- Whisper supports transcription in 50+ languages automatically
Troubleshooting
- If the health check fails or model weights cannot download, ask Novaplan to check the
faster-whisperpackage, backend connectivity tohuggingface.co, and model cache - If transcription is slow, try a smaller model or ask Novaplan whether GPU capacity is available
- If you get out-of-memory errors, try a smaller model or
int8compute type; Novaplan can check backend capacity - If a custom Model Cache Directory is configured, Novaplan should confirm that it exists and is writable by the workspace process